Case Studies
In-depth engineering case studies: the problem, the constraints, the architecture decisions, how it was built, and the measurable results.
Nothing matches that combination
Filters stack, so two narrow picks often come up empty even when each has results on its own.
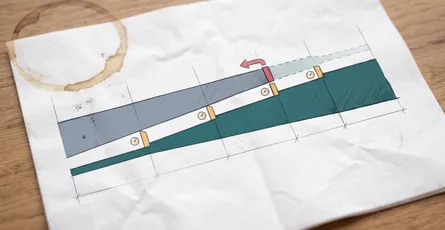
From Blue-Green to Progressive Delivery with Argo Rollouts
- DevOps & Automation
- Cloud Computing
- 03 Nov 2026
- 13 Mins read
The incident that started this was not caused by carelessness. It was caused by someone being careful. A release went out at 14:20 on a Tuesday. Error rate climbed within ninety seconds. The on-call
Secrets Management Migration to Vault Without an Outage
This project did not start with a security review. It started with a resignation. A senior engineer gave notice, and someone asked the reasonable question of what they could still log into after thei
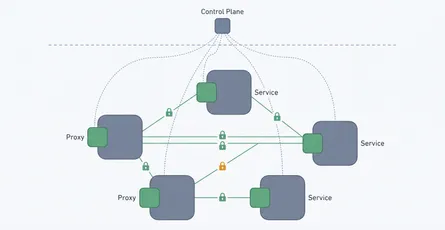
A Service Mesh Rollout That Was Worth It
- Architecture
- DevOps
- 20 Oct 2026
- 08 Mins read
The request that started this was not "can we have a service mesh". It was an auditor asking how we encrypted traffic between services, and the honest answer being that we mostly did not. Everything i
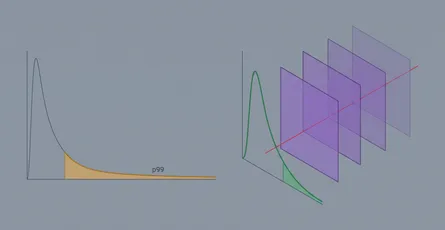
Cutting p99 Latency 60% with a Caching Rearchitecture
- Architecture
- Performance
- 13 Oct 2026
- 10 Mins read
The complaint that started this was not about speed. It was a support ticket saying the dashboard "sometimes doesn't load," from a customer whose account was roughly forty times larger than our median
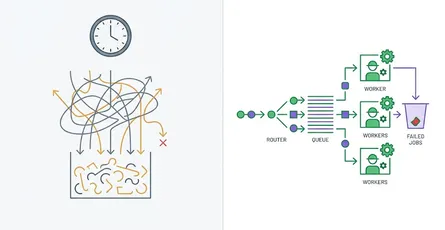
Replacing Cron Chaos with an Event-Driven Pipeline
- Cloud Architecture
- DevOps
- 06 Oct 2026
- 10 Mins read
The handover note said "check the pipeline runs" and nothing else. Behind that sentence were 41 cron jobs spread across 6 EC2 hosts, some chained by sleep 900 because someone had once needed job B t
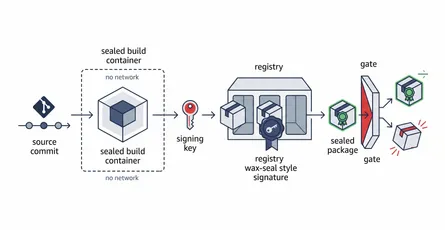
Hardening a CI/CD Supply Chain to SLSA Level 3
The question that started this was from an auditor, and it was a fair one: can you prove that the container running in production is the one your pipeline built from the commit you think it was? We ha
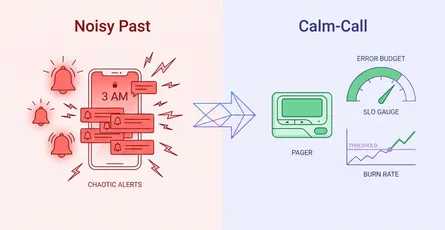
Taming a 3am Pager: SLOs and Error Budgets That Stuck
- Reliability
- DevOps
- 29 Aug 2026
- 07 Mins read
A platform team was losing people to burnout, and the cause was the pager. On-call meant a phone that went off day and night with alerts about CPU, memory, and pod restarts, the overwhelming majority
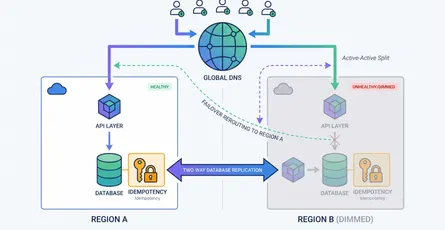
Multi-Region Active-Active for a Payments API
- Architecture
- Cloud Computing
- 16 Aug 2026
- 06 Mins read
A payments API that moves real money had been running comfortably in a single AWS region for years. It was reliable until the day it was not: a regional control-plane incident took the whole service o
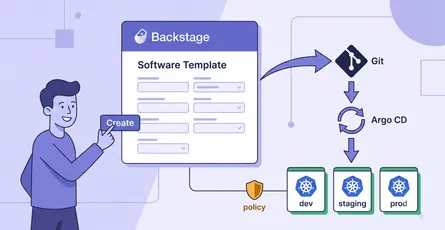
Building an Internal Developer Platform on Backstage and GitOps
- DevOps
- Platform Engineering
- 03 Aug 2026
- 09 Mins read
Product teams were spending more time waiting on the platform team than building features. Spinning up a new service meant opening a ticket and waiting for someone to provision a repo, wire up CI, wri
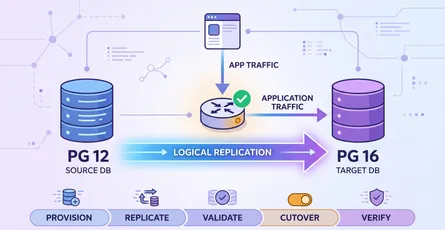
Zero-Downtime PostgreSQL Major-Version Upgrade at Scale
A multi-terabyte PostgreSQL 12 database was reaching end of life, and the business ran around the clock, so the usual answer of "schedule a maintenance window" was off the table. We upgraded it to Pos
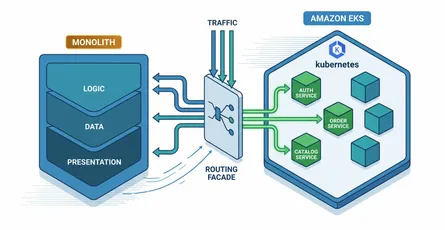
Migrating a Monolith to Kubernetes Without a Big-Bang Cutover
- DevOps
- Cloud Native
- 20 Jul 2026
- 07 Mins read
Almost every failed "let's move off the monolith" project shares one detail: the plan was a big-bang cutover. Rewrite in parallel, pick a weekend, flip the switch, and pray. This is the opposite of th
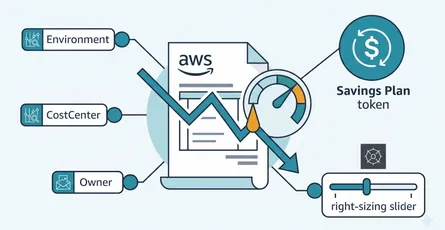
Cutting a SaaS AWS Bill 41% Without Slowing Delivery
- Cloud Computing
- DevOps
- 19 Jul 2026
- 10 Mins read
A growing SaaS ran on EKS with a full GitOps pipeline, and it was over its AWS budget nearly every month. The reflex from leadership was the usual one: freeze features until the bill comes down. That
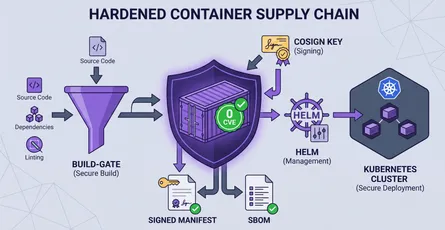
QuenchWorks: Building a 0-CVE Container Image and Helm Chart Catalog
When Bitnami moved its long-trusted catalog behind a paid tier, thousands of teams woke up to a supply-chain problem they didn't choose. The free images they had pinned in production would stop gettin