The complaint that started this was not about speed. It was a support ticket saying the dashboard “sometimes doesn’t load,” from a customer whose account was roughly forty times larger than our median account. Our latency dashboard showed a p50 of 90ms and a green tick, so for about three weeks nobody believed them.
They were right, and our monitoring was lying by omission. This is what we found, what we built, and the two ways caching made things worse before it made them better.
The problem
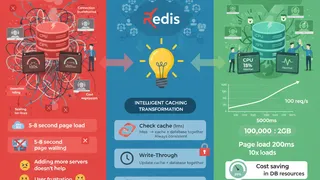
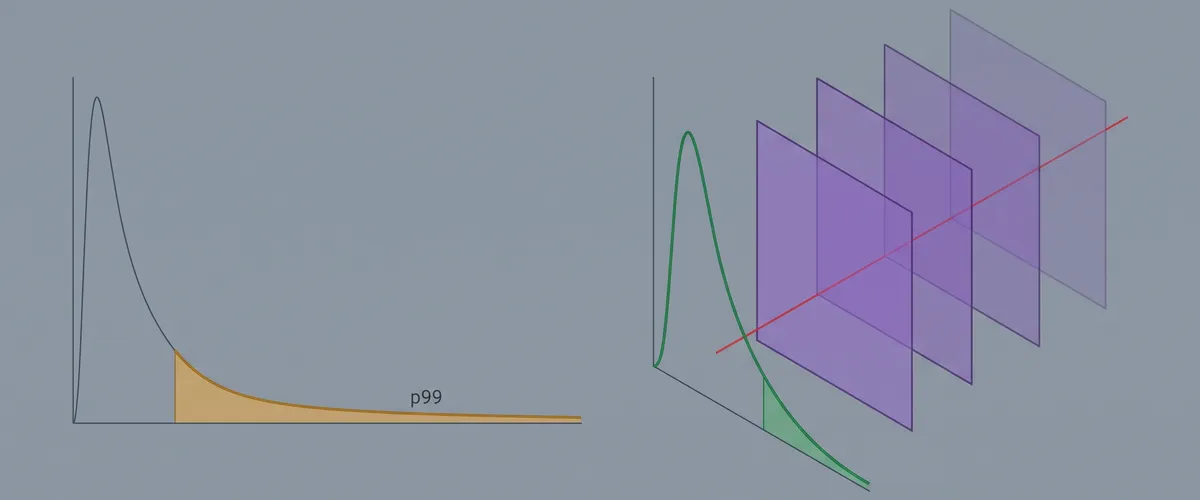
Our p99 sat at 4.2 seconds against a p50 of 90ms. That gap is the whole story. A 46x spread between the middle and the tail is not a system that is uniformly slow, it is a system where a small class of requests does something completely different from the rest.
We found the class by grouping traces by account size rather than by endpoint. The offender was GET /api/v1/projects, which built each row from a nine-table join covering the project, its owner, its current status, its two most recent activity entries, and a permissions check. On an account with three projects the endpoint ran that join three times and returned in 60ms. On the account that complained it ran 214 times, and the response took just over four seconds.
Two things made this worse than it sounds. The join included a correlated subquery against the activity table, which had grown past 400 million rows, so its cost scaled with account age rather than account size. And Aurora’s buffer pool was thrashing, because a handful of these large-account requests would evict the working set that every small-account request depended on. Those large-account requests slowed everyone else down too.
We spent the first sprint optimising the wrong thing, because the p50 said the system was fine and the p50 is what the dashboard showed by default.
Constraints
We could not rewrite the endpoint. It was consumed by a mobile client we did not control the release cadence of, and by two customer integrations, so the response shape was frozen.
Strong consistency was required for exactly one field. Project status drives a permissions check, and showing a stale value there is a security problem rather than a cosmetic one. Everything else in the payload could be a few minutes old without anyone caring, which turned out to be the most useful thing we learned during scoping.
We had a fixed budget of one engineer for six weeks, and a hard rule from the incident review that no change could increase the blast radius of an Aurora failover.
Architecture
Four layers, and the discipline that made them useful was insisting each one answers a different question. When two layers answer the same question you get double the invalidation work for one layer of benefit.
Layer 1 is CloudFront, caching whole responses for the endpoints that have no per-user content. This covered less than we hoped. Most of our traffic is authenticated and account-scoped, so the CDN mainly earns its place on static assets and three public endpoints.
Layer 2 is a CloudFront Function on the viewer request, and it is the layer people skip. Its only job is to normalise the cache key: sort query parameters, drop the tracking ones, lowercase the path, and collapse ?page=1 to the canonical no-parameter form. Before this, ?sort=name&page=1 and ?page=1&sort=name were two cache entries for one response. Normalising the key raised the CDN hit ratio from 31% to 68% without touching a single cache TTL, which is the cheapest performance work in this entire project.
Layer 3 is ElastiCache for Redis, holding assembled objects rather than query results. This is the layer that fixed the actual problem. A single project’s rendered JSON is cached under project:v3:{id}, so the 214-row request becomes one MGET of 214 keys plus however many of those missed. On a warm cache that is a single round trip.
Layer 4 is a DynamoDB table holding a flattened read model of the same data, with DAX in front of it. This exists because a cold Redis is not an edge case, it is Tuesday. When we deploy a schema change and flush a key prefix, the request that arrives one millisecond later needs somewhere better to land than the nine-table join.
Tip
Version your cache keys. The v3 in project:v3:{id} is a literal in the code, and bumping it is how we ship a payload shape change. There is no flush, no migration and no window where a new deployment reads an old shape, because the new code simply asks a different question. Old keys expire on their own.
Keys, TTLs, and the stampede
The cache key is where this project nearly died. Our first implementation built the key from the incoming request, which meant it included a header our load balancer sets per request. The hit ratio was zero. Redis filled with single-use entries, evicted them, and we reported a 4% improvement to the team because the p99 had moved inside noise. It took two weeks and a colleague asking “why is the key cardinality higher than our user count” to catch it.
TTLs are 300 seconds for project objects and 60 seconds for anything containing the status field, which is short enough that the consistency requirement is met by expiry alone rather than by invalidation.
Both numbers carry jitter, and this matters more than the numbers do:
import random
BASE_TTL = 300JITTER = 0.10 # plus or minus 10 percent
def ttl_for(key: str) -> int: """Spread expiry so keys written together do not expire together.""" spread = int(BASE_TTL * JITTER) return BASE_TTL + random.randint(-spread, spread)Without jitter, a deployment that warms 10,000 keys in one second produces 10,000 keys that expire in one second, and five minutes after every deploy the origin gets a spike shaped exactly like the warm-up. We saw this twice before adding the jitter, and both times misread it as a traffic pattern.
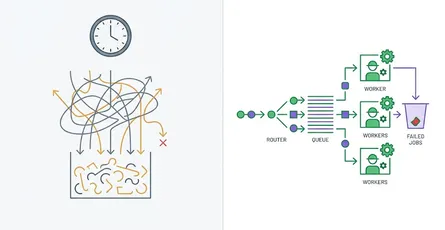
Stampede protection is a single-flight lock. On a miss, one request wins the lock and queries the origin, and the others wait for the result rather than piling onto Aurora:
The lock is a plain SET lock:{key} {token} NX PX 5000. Whoever gets OK fetches, everyone else sleeps and re-reads up to three times. This is not a distributed lock in the correctness sense, and it does not need to be. If it fails and two requests query the origin, the outcome is one redundant query, not a wrong answer.
Implementation
We shipped in four passes, deliberately smallest-blast-radius first.
-
Normalise the cache key at the edge. One CloudFront Function, no application change, immediately measurable on the CDN hit ratio. This shipped on day three and produced the single largest hit-ratio gain of the project.
-
Add Redis reads behind a feature flag, writing nothing. For a week the code fetched from Redis, fetched from Aurora, compared the two, and logged mismatches while always serving the Aurora result. This is the step that is easy to skip and expensive to skip. It found two bugs in our serialisation before either could serve a wrong answer to a customer.
-
Turn on Redis serving, per account, starting with internal accounts and then the smallest 10% of customers. Roll forward by hit ratio and mismatch rate rather than by calendar.
-
Backfill the DynamoDB read model and wire the DAX path as the miss fallback. This went last because it was the only step that needed a data migration.
Invalidation is event-driven and has exactly one writer. Application code never deletes a cache key directly. It publishes what changed, and a single Lambda owns the mapping from a domain change to the set of keys that change touches.
# The whole point: one place knows that touching a project also# invalidates its owner's project list and the account rollup.KEY_MAP = { 'project.updated': lambda e: [f"project:v3:{e['project_id']}", f"projectlist:v3:{e['account_id']}"], 'project.deleted': lambda e: [f"project:v3:{e['project_id']}", f"projectlist:v3:{e['account_id']}", f"rollup:v2:{e['account_id']}"], 'member.role_set': lambda e: [f"projectlist:v3:{e['account_id']}"],}
def handler(event, _context): detail = event['detail'] keys = KEY_MAP[event['detail-type']](detail) if keys: redis.delete(*keys) return {'invalidated': len(keys)}Scattering redis.delete calls through the codebase is how you get stale reads that nobody can trace. Every one of our early staleness bugs was a write path that forgot one of the three keys it should have touched, and centralising the map is what stopped them recurring.
Careful here
We do not use KEYS or pattern-based deletion anywhere. KEYS project:* on a production Redis blocks the server while it scans every key in the keyspace, and our first invalidation implementation used it. It worked in staging with 400 keys and caused a 900ms stall in production with 2 million. If you need prefix deletion, either maintain a set of keys per prefix or version the prefix and let the old one expire.
Results
All figures below are measured from CloudWatch and our APM over the four weeks before and the four weeks after the final rollout, at comparable traffic.
| Metric | Before | After | Note |
|---|---|---|---|
p99 latency, GET /projects | 4.2s | 1.6s | measured, 62% reduction |
| p50 latency, same endpoint | 90ms | 71ms | measured, and never the problem |
| p99 for the largest account | 9.8s | 2.1s | measured |
| CDN hit ratio | 31% | 68% | measured, from key normalisation alone |
| Redis hit ratio, steady state | n/a | 94% | measured |
| Aurora read IOPS | baseline | down 71% | measured |
| Aurora reader instances | 3 | 1 | the cost saving that paid for the work |
The p50 barely moved, and that is the result worth internalising. We spent six weeks and improved the typical request by 19ms. What we actually bought was the tail, and the tail is where the customers who complain live.
Removing two Aurora readers covered the ElastiCache and DynamoDB spend with room left over, so the rearchitecture was cost-neutral in month one and slightly positive after.
Lessons
Caching moved our failure mode, it did not remove it. We traded slow responses for stale ones, and a slow response is loud while a stale one is silent. Two of our three post-rollout incidents were correctness bugs. Neither triggered a latency alert, because both were fast.
The compare-without-serving week was the highest-value thing we did. It cost five days and caught two serialisation bugs that would have served wrong data to real customers. Every time I have skipped that step on a caching project I have regretted it.
Measure the key, not just the hit ratio. A zero hit ratio looked like “caching does not help much here” for two weeks. Tracking key cardinality against expected cardinality would have caught it on day one, and it is now a dashboard panel.
Stale-on-error is a reliability feature disguised as a caching detail. Keeping values in Redis past their TTL, and serving them when the origin is unhealthy, turned one Aurora failover from an outage into a period of slightly old data. That was not in the original design. We added it after an incident and it has since earned its place twice.
The cheapest layer was the one we almost skipped. Normalising the cache key at the edge took one afternoon and produced a larger hit-ratio improvement than any TTL tuning we did afterwards. Before adding a layer, check whether the layer you have is being asked coherent questions.
Frequently Asked Questions
We did both eventually, but caching came first for a practical reason: the response shape was frozen by clients we did not control, and the nine-table join encoded business rules that several teams depended on. Caching bought us the tail-latency fix in six weeks without touching that logic. The query itself got rewritten the following quarter, once the cache meant we could change it without a latency regression being customer-visible.
We do not cache it for long. The project status field drives a permissions check, so anything containing it carries a 60 second TTL rather than 300, and the invalidation Lambda also deletes those keys on the relevant events. The belt-and-braces approach is deliberate. TTL alone is the guarantee, and invalidation is the optimisation that usually makes it faster than the TTL.
Not in the strict sense, and it does not need to be. If the lock is lost during a failover, the worst outcome is that two requests query Aurora for the same key instead of one. That is a duplicated read, not a wrong answer or a lost write. Reaching for something like Redlock here would add real complexity to prevent an outcome we are happy to accept.
Because the problem is not capacity, it is a cold cache. After a deploy that bumps a key version, or a node replacement, Redis is empty and every request goes to the origin at once. A bigger Redis is just as empty. The read model gives a cold miss somewhere cheap to land, so the worst case is a DynamoDB lookup rather than a nine-table join.
Roughly, from our measurements: the edge key normalisation produced the largest CDN hit-ratio gain but a modest p99 change, because the CDN was not serving the slow endpoint. Redis object caching accounts for most of the p99 reduction. The DynamoDB read model contributes almost nothing in steady state and everything in the ten minutes after a deploy, which is exactly what it was built for. We could not have predicted that split in advance, which is an argument for shipping layers one at a time and measuring between them.
Add the cardinality dashboard before the cache, not after the bug. And spend a day writing down which fields genuinely need to be current before touching any code. That single conversation is what let us use a 60 second TTL for one field and 300 for everything else, instead of the 30 seconds everywhere that our first design proposed. Uniform TTLs are almost always a sign that nobody asked the question.
References
- Amazon ElastiCache caching strategies and best practices
- Amazon CloudFront cache key and origin request settings
- Writing CloudFront Functions for viewer request events
- Amazon DynamoDB Accelerator (DAX) developer guide
- Redis SET command, including NX and PX options
- Distributed locks with Redis, including why the simple form is usually enough
- Amazon Aurora replication and reader endpoints
- RFC 5861, the stale-while-revalidate and stale-if-error Cache-Control extensions