Why does Kubernetes make storage this complicated?
The short version
Hey, want your data to still be there after a restart? Then you need to understand three objects instead of one. That feels like overhead until you see what it buys you.
A container’s filesystem dies with the container. That is deliberate, and it is what makes containers cheap to move around. But a database inside a container needs a disk that outlives it, and Kubernetes cannot just hand you “a disk” because it has no idea whether it is running on AWS, on bare metal, or on your laptop.
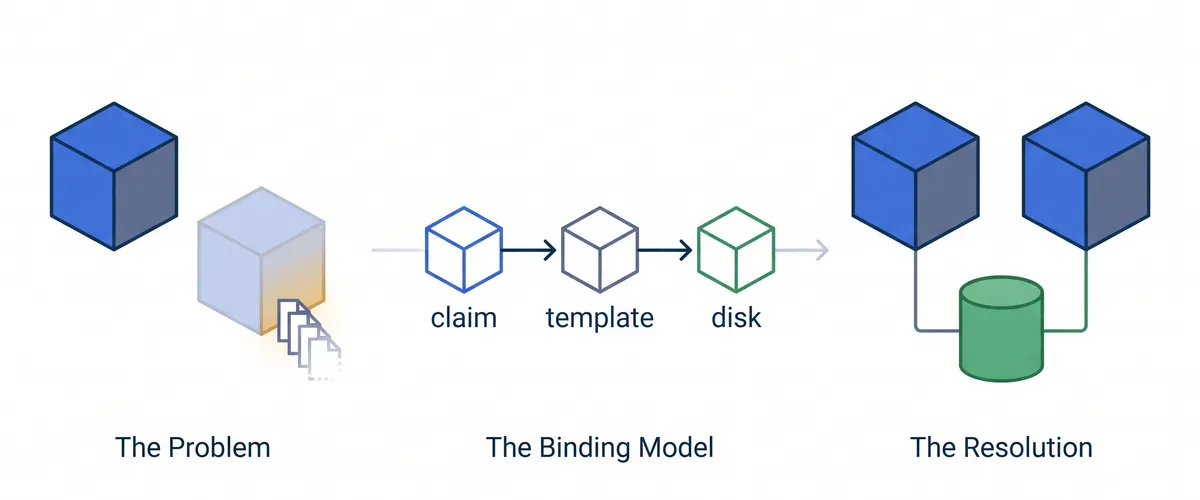
So it splits the problem. You describe what you want, something else figures out how to get it, and a third object represents the real thing once it exists.
The three objects, in one line each
- PersistentVolume (PV) is the real storage. An actual EBS volume, an NFS export, a directory on a node.
- PersistentVolumeClaim (PVC) is your request for storage. Size, access mode, and which StorageClass to use.
- StorageClass is the template that says how to create storage when someone claims it.
You write the PVC. Kubernetes and a driver produce the PV. Your pod mounts the PVC and never mentions the PV at all.
The problem with getting this wrong
What’s the issue?
Two failure modes, and both are quiet until they are not.
The first is data loss. A reclaimPolicy of Delete means that deleting the PVC deletes the underlying AWS volume, and the data in it, immediately and without a confirmation prompt. Delete a namespace and you delete every volume in it. This is the default on plenty of StorageClasses, including some that ship with managed clusters.
The second is a pod that will not start and does not clearly say why. An EBS volume exists in exactly one availability zone. If your pod is rescheduled into a different AZ, it cannot attach that volume, so it sits in Pending. The events mention volume node affinity conflict, which is technically accurate and not much help at 2am.
The real-world consequences
The AZ one usually surfaces during a node upgrade, which is the worst time for it, because you are already mid-maintenance and now a stateful workload is stuck. It also surfaces when a spot node goes away and the replacement lands somewhere else.
The reclaim policy one surfaces once, and then nobody on that team ever forgets it again.
The solution: understand the binding, then pick the right storage
What actually happens
Here’s how to fix it: stop thinking of a PVC as a disk and start thinking of it as an order you place. Then the sequence makes sense.
The step people skip is the CSI driver. It is the thing making the actual AWS API call, it runs in your cluster, and on EKS it needs its own IAM role through IRSA. A PVC stuck in Pending with no PV appearing is that permission missing about half the time.
The two StorageClasses worth having
Most clusters need exactly two. One for fast single-writer block storage, one for shared storage.
# EBS gp3. Your default for databases and anything single-writer.apiVersion: storage.k8s.io/v1kind: StorageClassmetadata: name: ebs-gp3provisioner: ebs.csi.aws.comparameters: type: gp3 encrypted: 'true'reclaimPolicy: Retain # deliberate: a deleted claim should not delete the diskallowVolumeExpansion: truevolumeBindingMode: WaitForFirstConsumer # the AZ fix, see belowvolumeBindingMode: WaitForFirstConsumer is the single most valuable line there. The default, Immediate, creates the volume as soon as the PVC exists, before the scheduler has decided where the pod is going. That is how you get a volume in eu-west-1a and a pod that would have been happier in 1b. WaitForFirstConsumer makes the driver wait until the pod is scheduled, then create the volume in the right zone.
allowVolumeExpansion: true costs nothing and lets you grow a volume later by editing the PVC. Without it you are taking a snapshot and restoring into a bigger volume, at 3am, during the incident where you ran out of disk.
For shared storage, EFS:
# EFS. The only common way to get ReadWriteMany on AWS.apiVersion: storage.k8s.io/v1kind: StorageClassmetadata: name: efs-sharedprovisioner: efs.csi.aws.comparameters: provisioningMode: efs-ap # one access point per volume fileSystemId: fs-0123456789abcdef0 directoryPerms: '700'reclaimPolicy: RetainTools and platforms
On EKS the two you want are the AWS EBS CSI driver and the AWS EFS CSI driver, both installable as EKS add-ons, which is easier than the Helm route and keeps upgrades in the same place as the cluster. Both need an IAM role attached to their service account.
If you need snapshots, add the external-snapshotter controller and use VolumeSnapshot objects. EKS does not install it for you, and kubectl get volumesnapshot returning “no resources found” on a fresh cluster usually means the CRDs are simply not there.
Quick implementation steps
The short list
Quick takeaways
- Install the CSI driver as an EKS add-on, and give it an IAM role through IRSA.
- Create two StorageClasses:
ebs-gp3for single-writer,efs-sharedforReadWriteMany. - Put
volumeBindingMode: WaitForFirstConsumeron every block-storage class. - Set
reclaimPolicy: Retainon anything holding data you would miss. - Turn on
allowVolumeExpansionbefore you need it. - Use
volumeClaimTemplatesin StatefulSets, never a shared PVC.
Let Kubernetes name the StatefulSet claims
A StatefulSet does not use a PVC you wrote. It uses a template and creates one claim per replica.
apiVersion: apps/v1kind: StatefulSetmetadata: name: postgresspec: serviceName: postgres replicas: 3 selector: matchLabels: {app: postgres} template: metadata: labels: {app: postgres} spec: containers: - name: postgres image: postgres:17 volumeMounts: - name: data mountPath: /var/lib/postgresql/data volumeClaimTemplates: - metadata: name: data spec: accessModes: ['ReadWriteOnce'] storageClassName: ebs-gp3 resources: requests: storage: 20GiThat produces data-postgres-0, data-postgres-1, and data-postgres-2. The names are predictable, which is the whole point: postgres-1 restarts and gets data-postgres-1 back, every time, because the claim is tied to the ordinal rather than to the pod instance.
Two things worth knowing. Deleting the StatefulSet does not delete those PVCs, which is a safety feature and also a slow storage leak if you delete and recreate a lot. And scaling down leaves the higher-numbered claims behind, waiting for you to scale back up.
Access modes, plainly
| Mode | Means | On AWS |
|---|---|---|
ReadWriteOnce | One node can mount it read-write | EBS |
ReadOnlyMany | Many nodes, read-only | EFS, or an EBS snapshot restore |
ReadWriteMany | Many nodes, all read-write | EFS only |
ReadWriteOncePod | Exactly one pod, not one node | EBS, and stricter than RWO |
ReadWriteOnce is per node, not per pod. Two pods on the same node can both mount the same RWO volume, which surprises people who assumed it was a lock. ReadWriteOncePod is the one that actually guarantees a single writer.
Benefits of getting the storage layer right
Why it helps
The failures it prevents are the expensive kind. Storage bugs do not degrade gracefully. A stateless service with a bug returns errors and you roll back. A storage misconfiguration loses data, and there is no rolling back from that.
What you actually get
Dynamic provisioning means nobody files a ticket to get a disk. A developer writes 8 lines of YAML and a volume exists, encrypted, in the right zone, with expansion enabled.
Predictable identity means stateful workloads stop being scary. A Postgres replica in a StatefulSet can be killed, rescheduled, and upgraded, and it comes back attached to its own data.
And a deliberate reclaim policy means the blast radius of kubectl delete namespace is bounded. That command is going to get typed against the wrong context eventually. Whether it is a bad afternoon or a resume-updating afternoon depends on a single line you wrote months earlier.
What’s your approach?
Community discussion
What’s your take? I want to know how you handle the EFS question specifically, because it is the one I still see teams get stuck on. Plenty of workloads ask for ReadWriteMany when what they actually need is object storage and a small code change. Do you push back on that, or is it easier to give them EFS and move on?
Share your experience
If you have been through a volume-related incident, the details are worth more than the general advice. Which failure was it: the AZ pin, the reclaim policy, a full disk with expansion disabled, or something better than all three? And did the events tell you what was wrong, or did you find it by reading the CSI driver logs?